Stages of AI tuning
, 3 min read
AI customization is a spectrum. At one end is zero-cost prompt engineering; at the other is pre-training a large language model (LLM) from scratch. Each stage brings different levels of complexity, data requirements and organizational investment. Understanding the stages helps you pick the right approach for your business or research needs.
The four stages
The main strategies for tuning or customizing an AI model are:
-
Prompt engineering
At the simplest end of the spectrum lies prompt engineering. Instead of altering the model's parameters, you craft carefully worded prompts to guide its outputs. It needs no additional data or lengthy training. It's quick, cost-effective and gives immediate improvements, but offers less fine-grained control.
-
Retrieval-augmented generation (RAG)
RAG brings external knowledge sources, such as a vector database or an up-to-date knowledge base, into the model's responses. By retrieving relevant information at query time, the model can give more accurate and contextually rich answers without retraining. It adds complexity and inference cost, but remains a powerful way to update the model's "knowledge" on the fly.
-
Fine-tuning
For organizations that need more specialized control, fine-tuning is the next level. Training a pre-existing LLM on your domain-specific data refines its behavior and outputs. It requires labeled data, compute and a longer training period than prompt engineering or RAG, but it gives granular control over the model's performance and can significantly improve domain-specific accuracy.
-
Pre-training
The most resource-intensive end of the spectrum is pre-training an LLM from scratch on massive datasets. It provides maximum control and a tailor-made model architecture aligned with your needs. It also demands significant time (often weeks or months), computational power and large-scale curated data. It's typically pursued by large organizations or research teams aiming for pioneering innovations.
Visualizing the spectrum
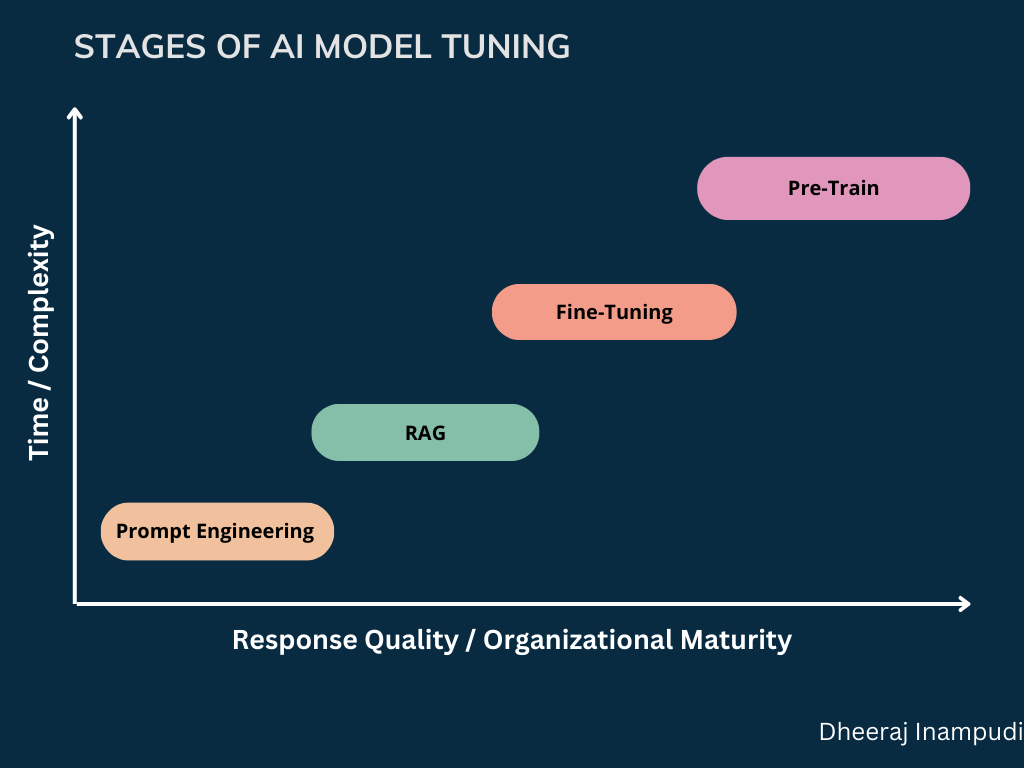
The chart above plots these stages against time/complexity and response quality/organizational maturity. As you move from prompt engineering to RAG, then to fine-tuning and finally pre-training, both the resource investment and the level of achievable specificity increase.
Detailed comparison
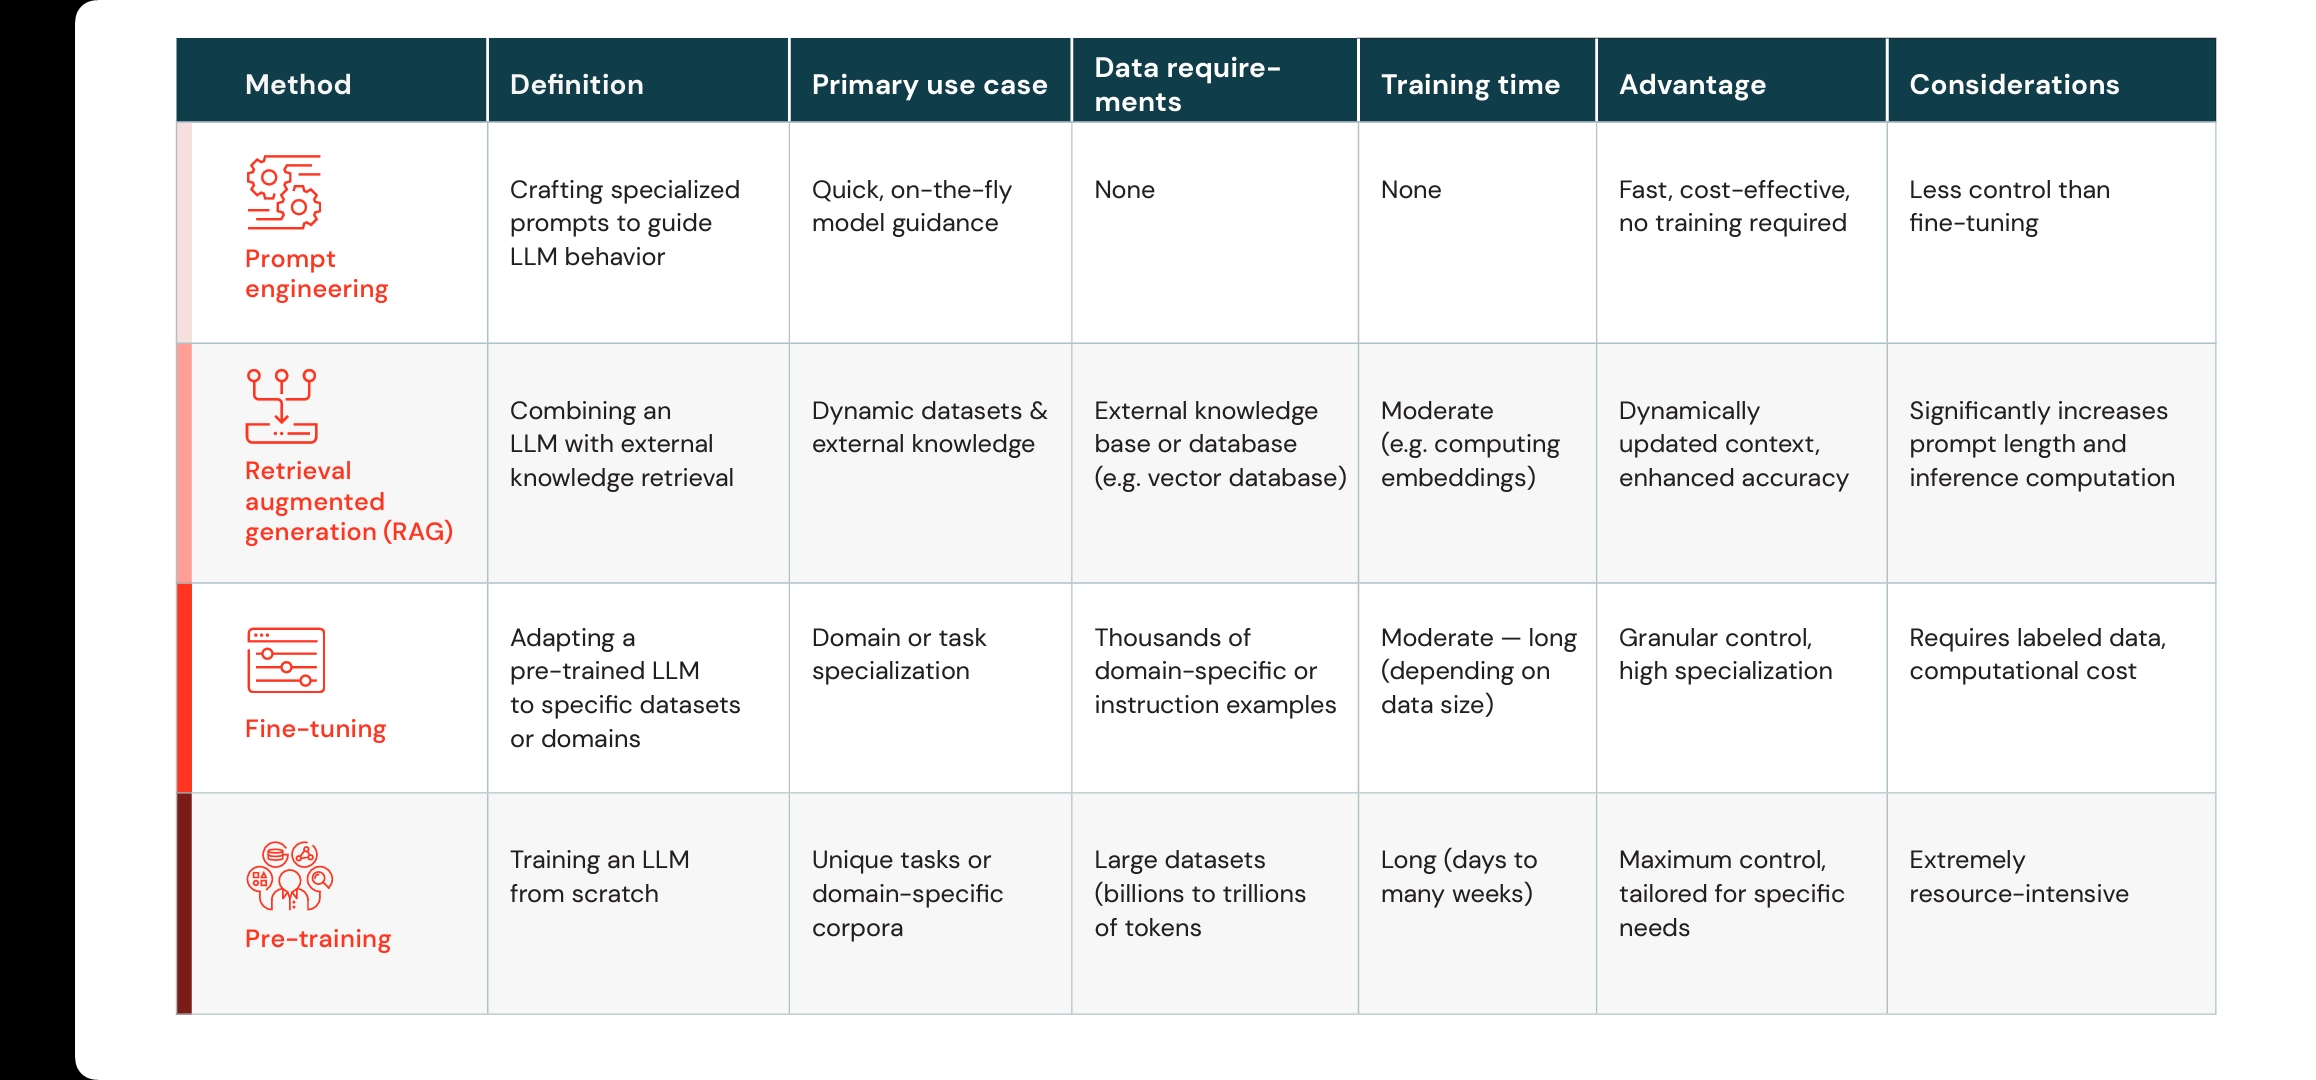
Source: Databricks blog.
The table above compares the methods across these attributes:
| Method | Data requirements | Training time | Advantages | Considerations |
|---|---|---|---|---|
| Prompt engineering | None | None | Fast and cost-effective | Limited control |
| RAG | External knowledge base | Moderate (e.g., computing embeddings) | Dynamically updated context | Longer prompts and increased inference costs |
| Fine-tuning | Thousands of domain-specific samples | Moderate to long (depending on dataset size) | Granular domain specialization | Requires labeled data and more compute |
| Pre-training | Billions to trillions of tokens | Long (days to many weeks) | Maximum control and tailor-fit | Extremely resource-intensive |
Choosing the right approach
The right stage depends on your organization's goals, resources and maturity:
| If you need… | Start with |
|---|---|
| Immediate results, no additional data | Prompt engineering |
| Dynamic knowledge integration | Retrieval augmentation (RAG) |
| Specific domain expertise | Fine-tuning |
| Full control and customization | Pre-training |
By understanding each stage's trade-offs, you can invest in the approach that best fits your constraints and aspirations.